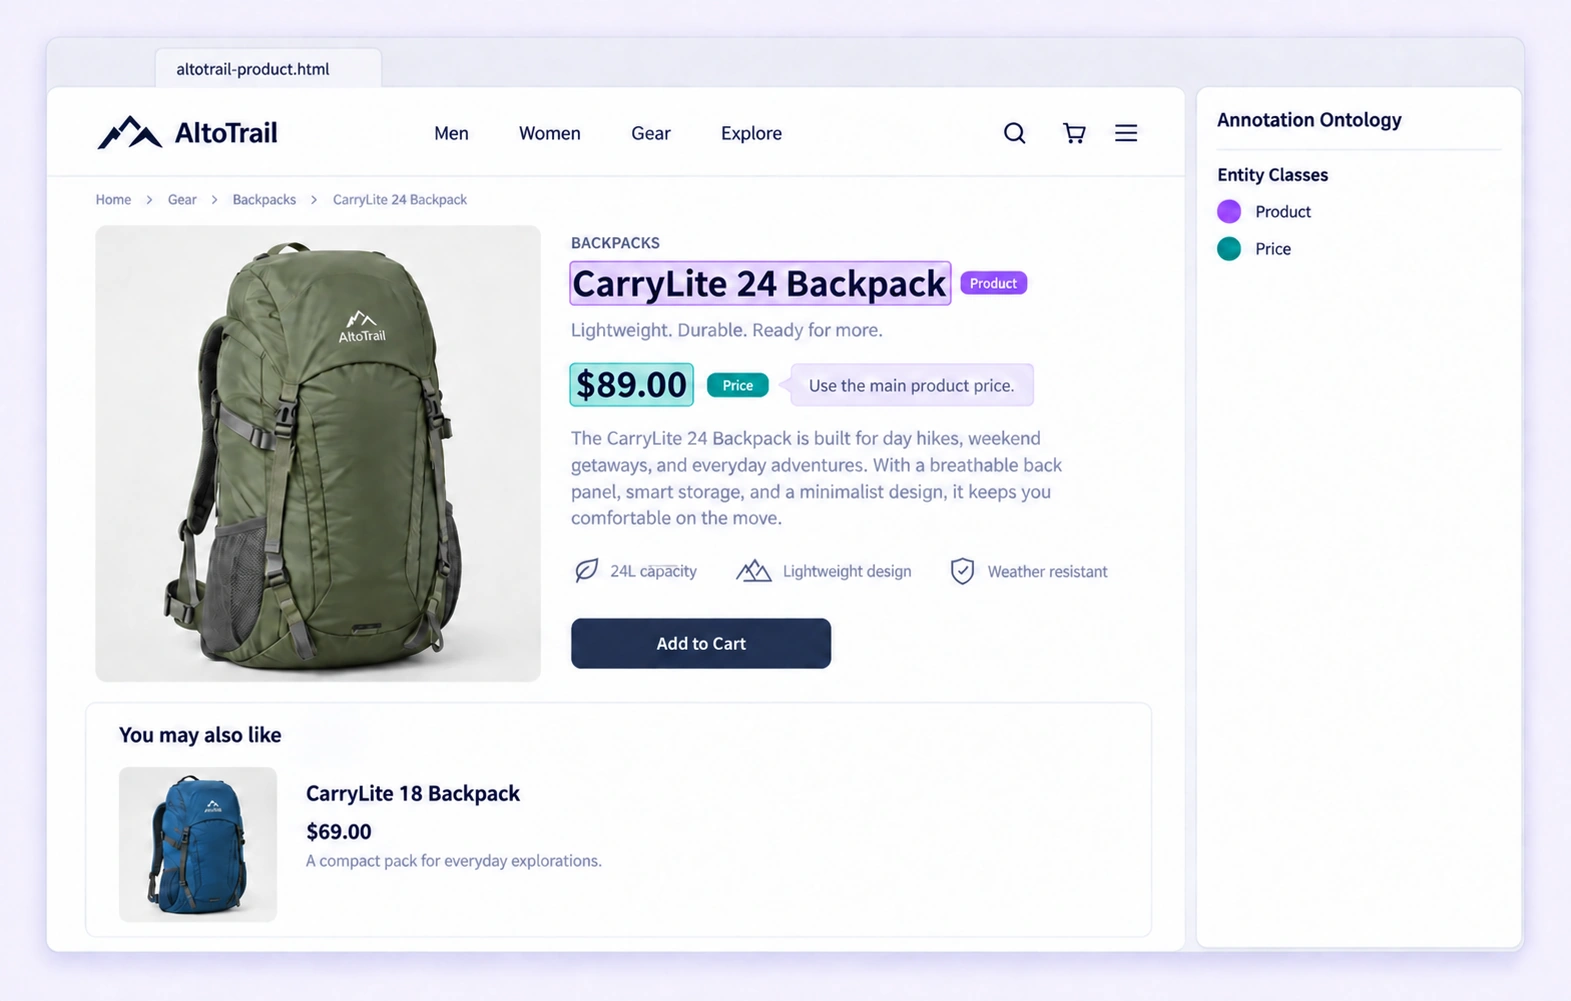
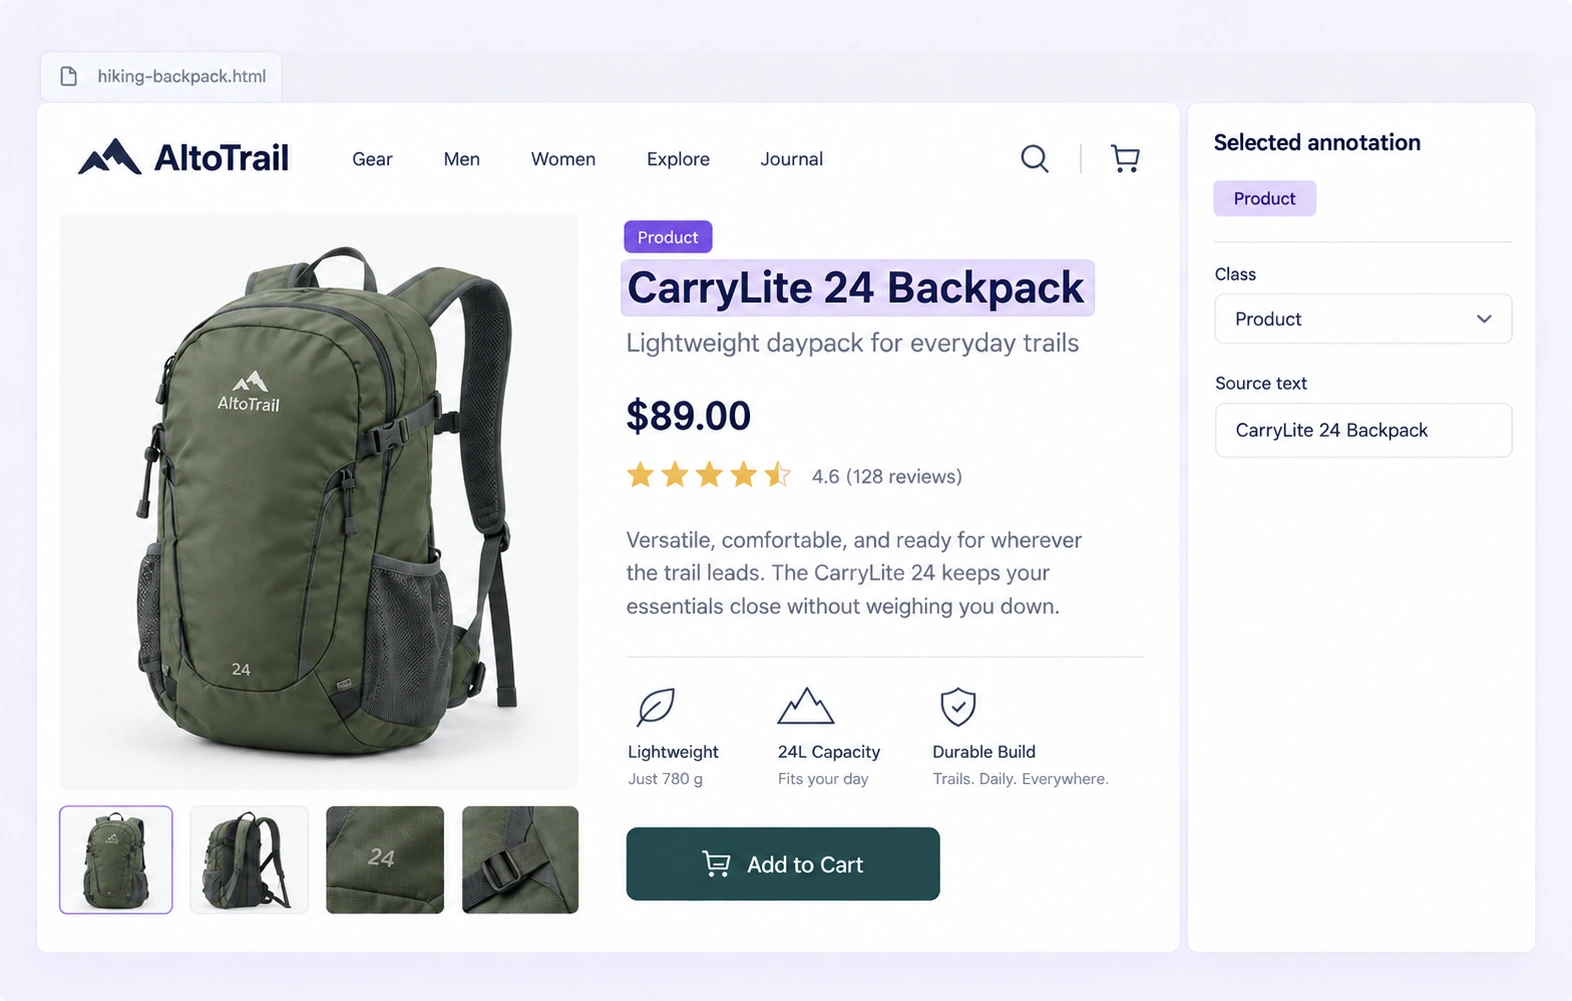
Product page annotation for information extraction

Label the product names, prices and specifications that extraction models need to identify. Keep each text label anchored to its uploaded HTML page while reviewers inspect the surrounding product context.
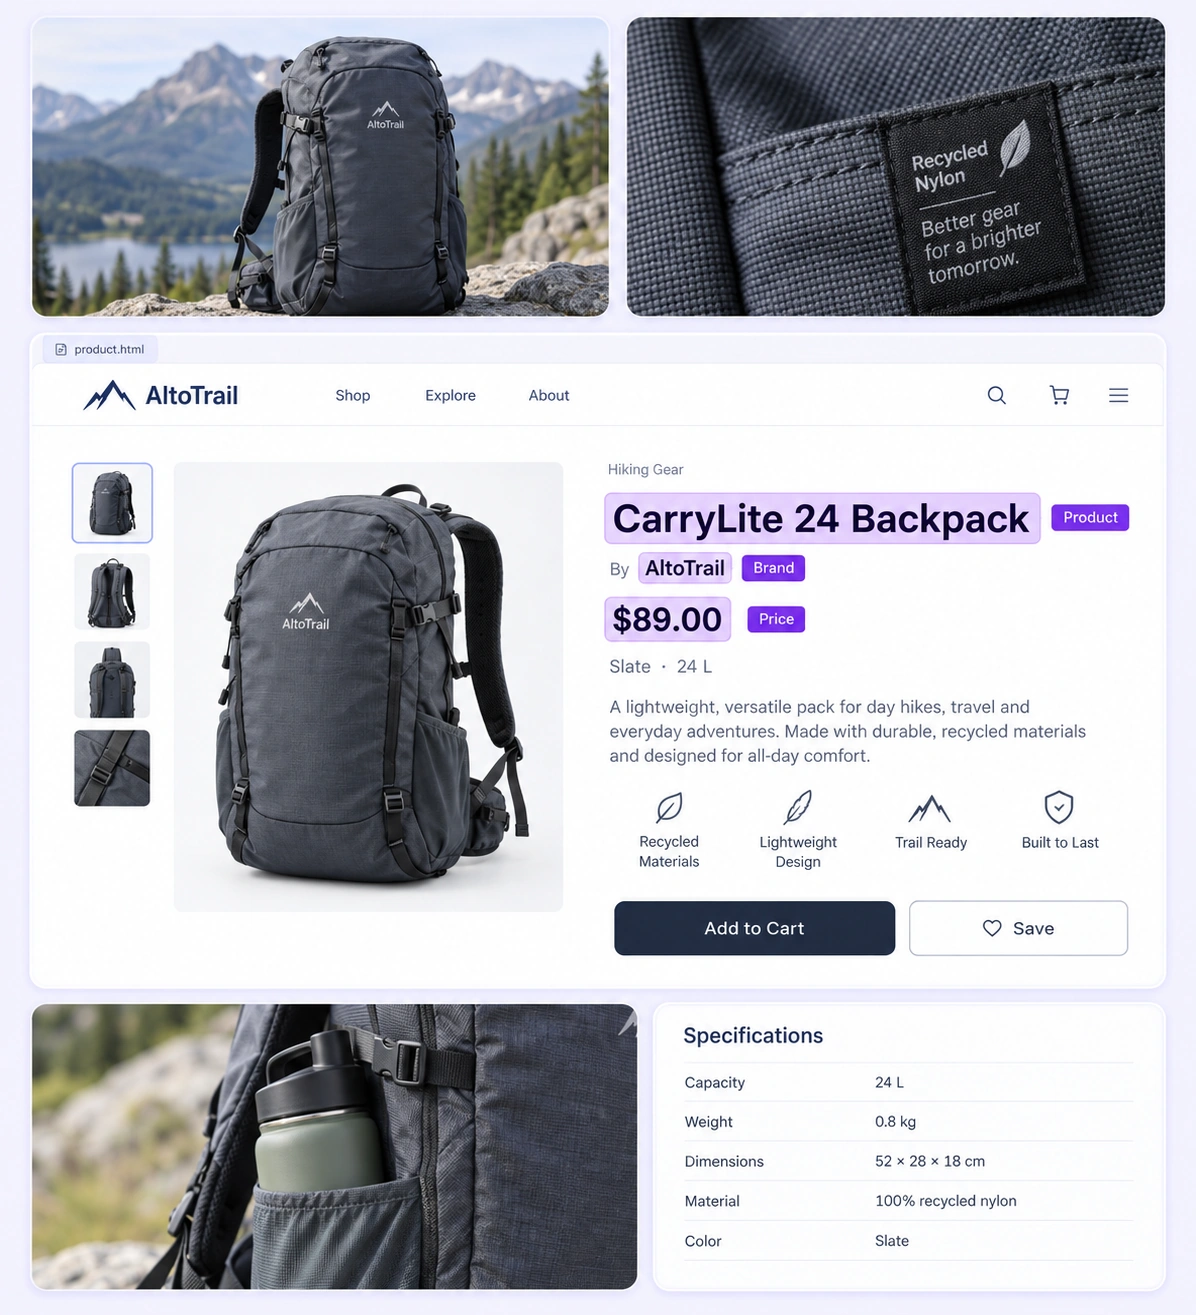
Product webpage collage with labeled product identity and offer

Turn product pages into reviewed extraction examples

Create consistent field labels across product titles, offer details and specifications without losing the rendered source context.
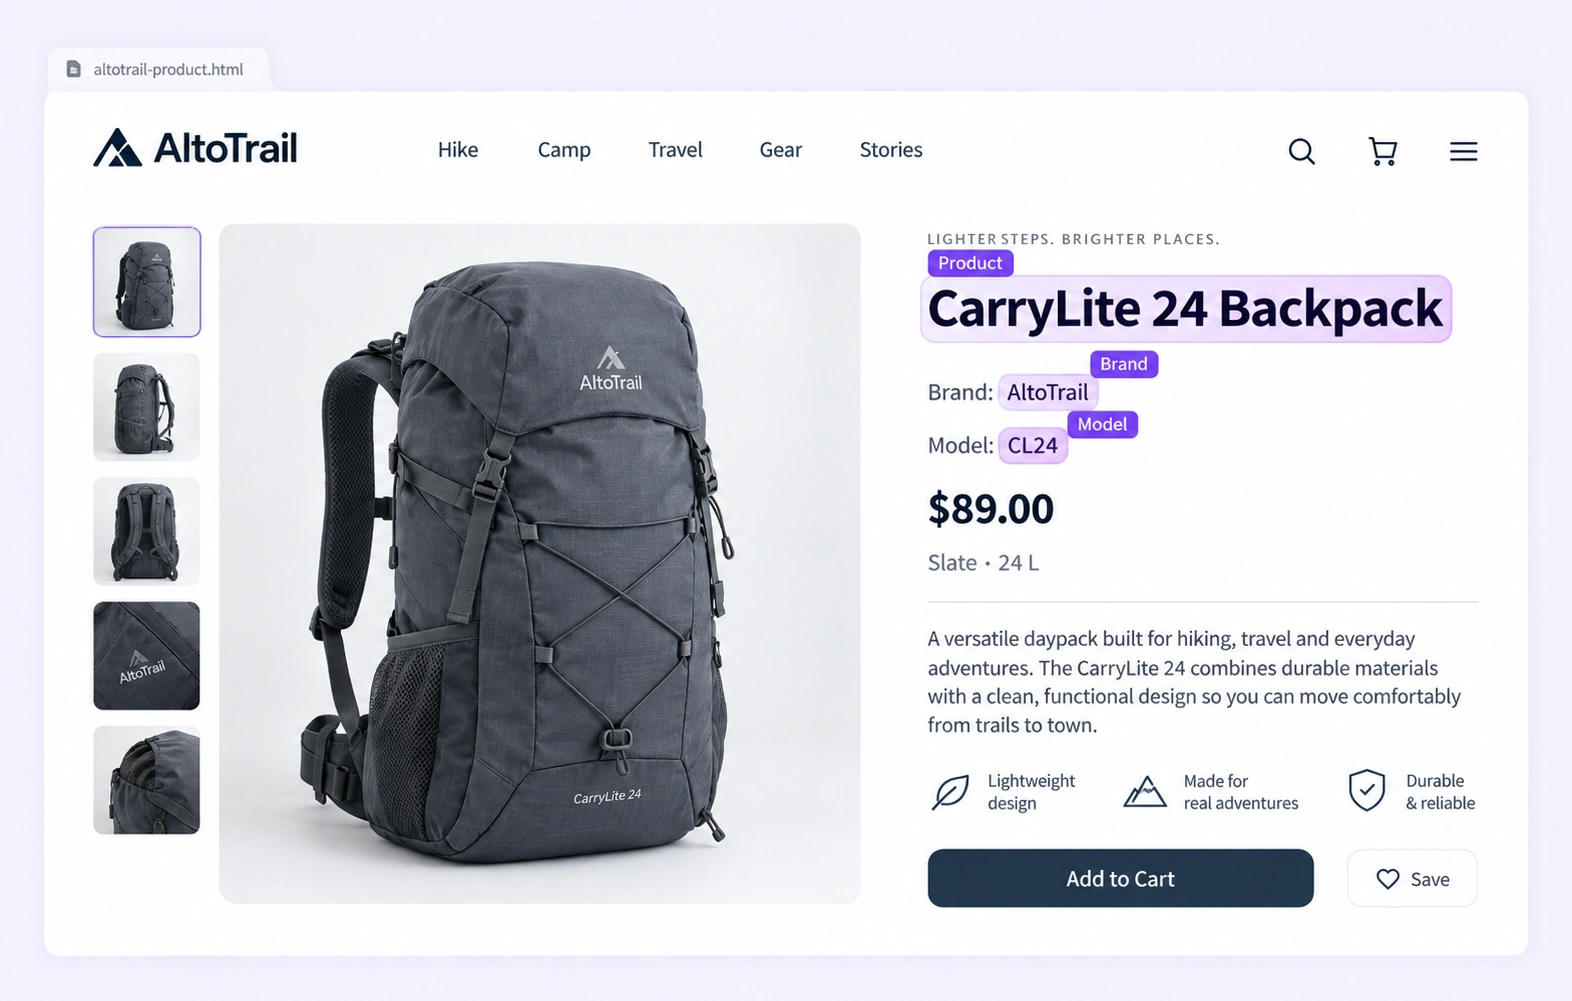
Product identity spans on a rendered backpack product page

Product identity fields

Label the product name, brand and visible model identifier. Keep the selected occurrence tied to the main product rather than a recommendation elsewhere on the page.
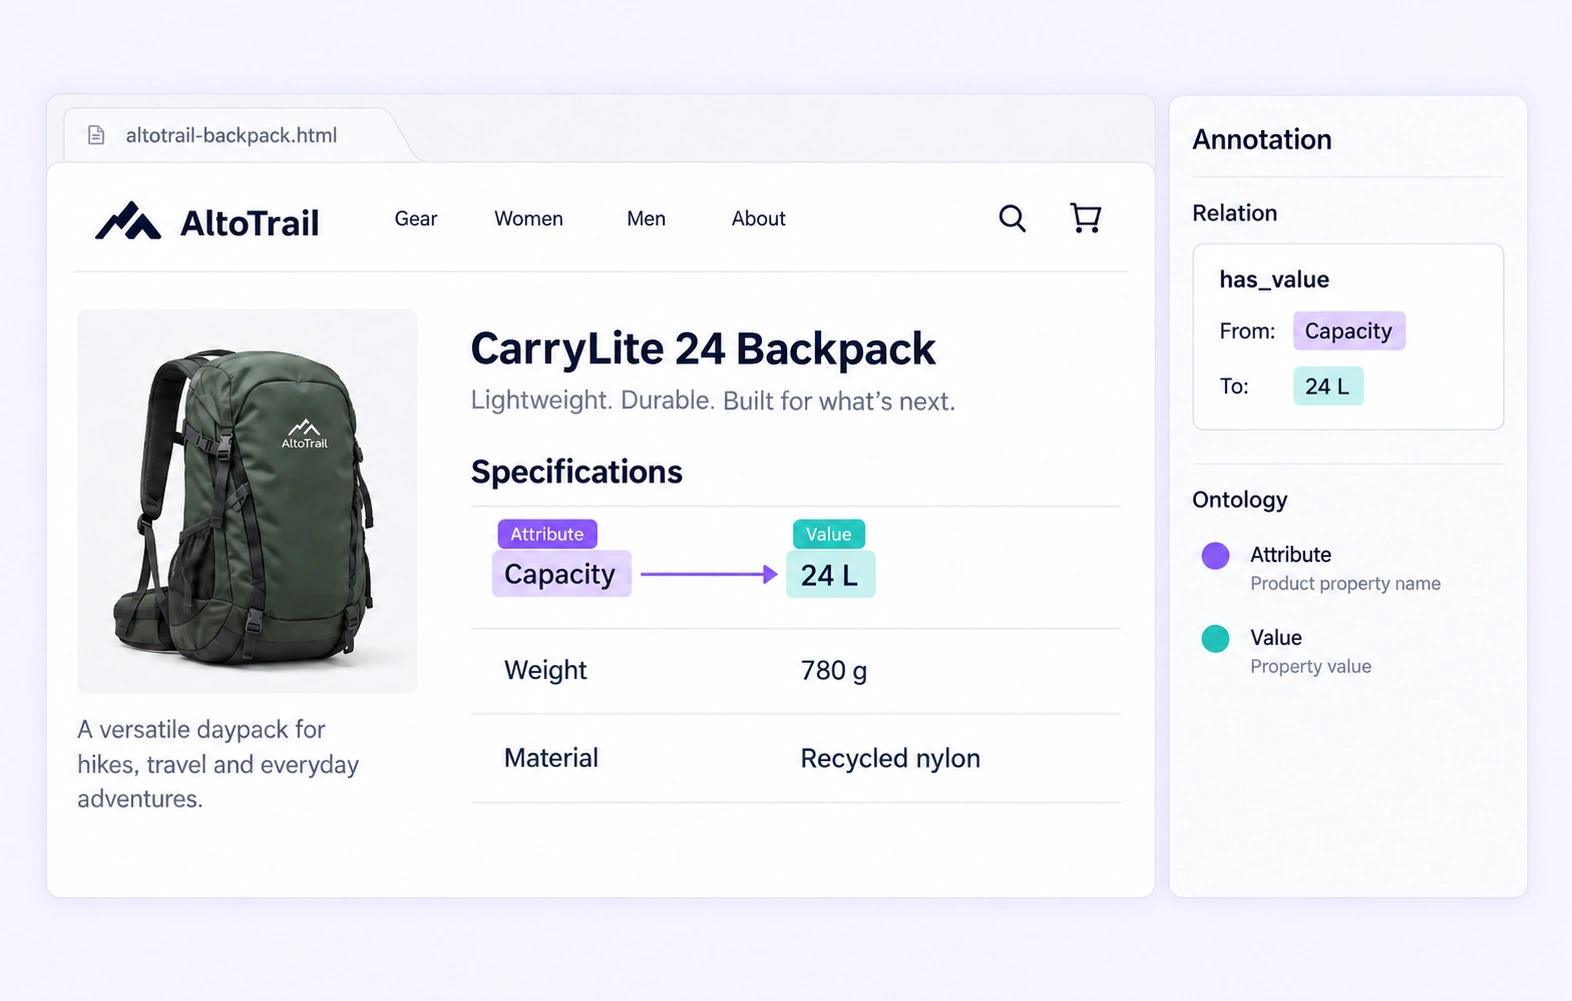
Specification names and values linked in the same HTML snapshot

Specification names and values

Select visible specification names and values as separate entities. Connect the matching pair with a defined relation, including fields presented in lists or tables.
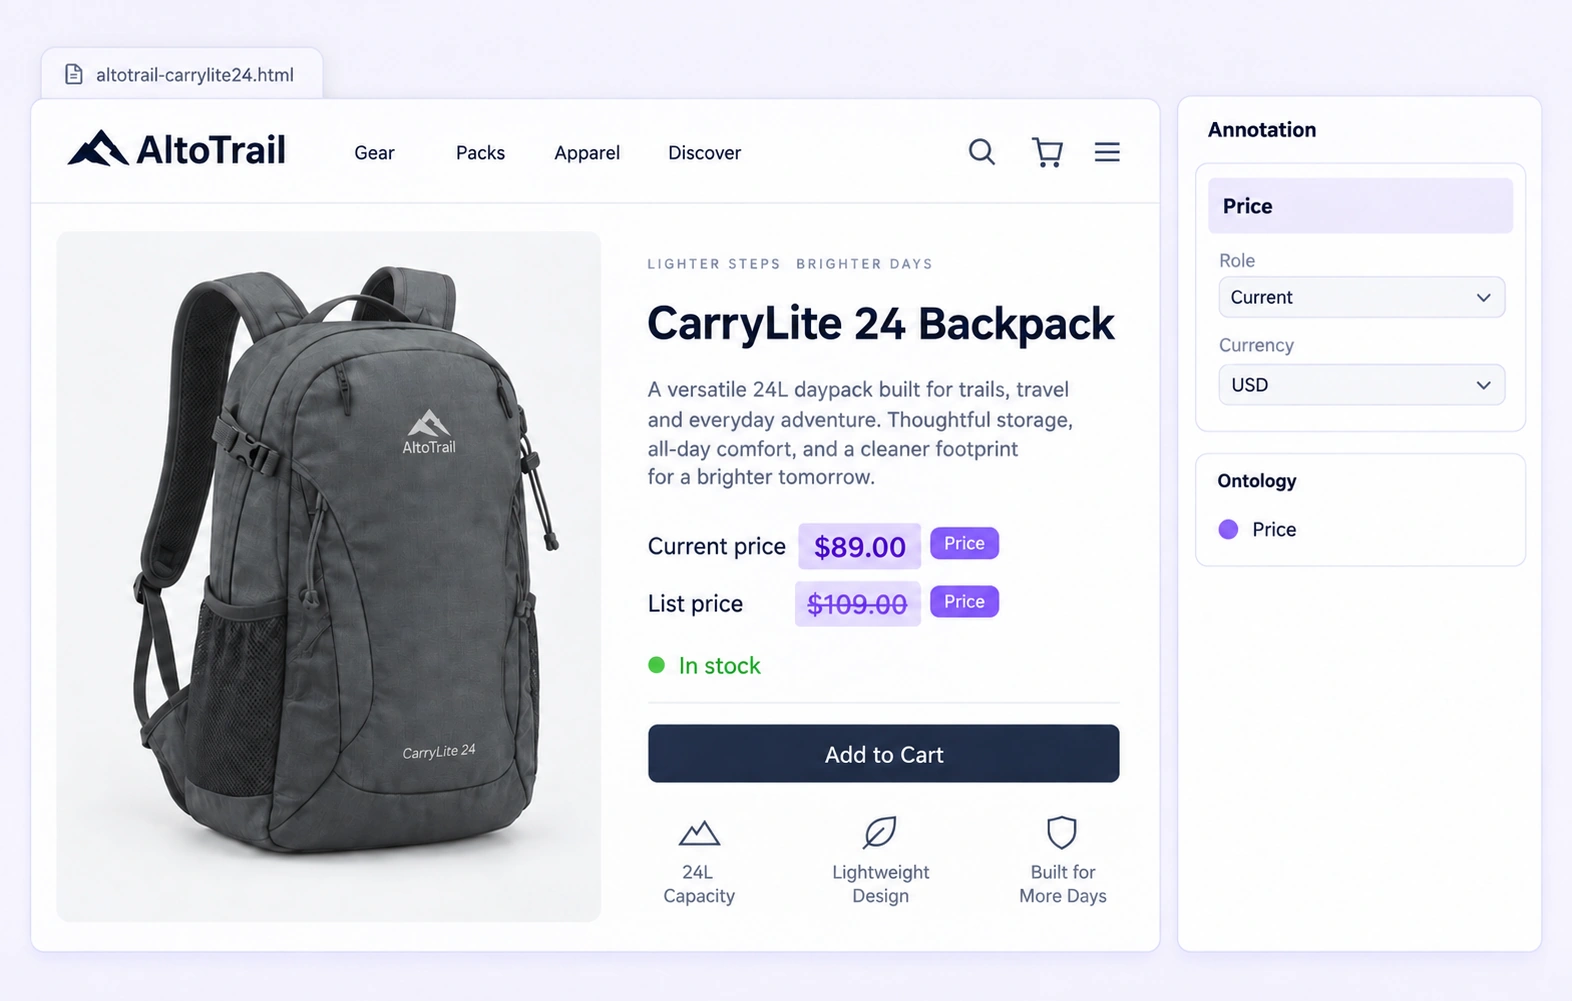
Different labeled price roles on a product offer

Prices and offer context

Distinguish the displayed sale price, list price and availability using explicit classes or properties. Label what the saved page states, including the currency and offer context required by your schema.
Reviewing the correct product occurrence among recommendations

Repeated-field review

Review repeated product names and prices in recommendations, bundles or page sections. Correct labels that point to the wrong occurrence before accepting the extraction example.

Why AI Teams Choose Unitlab

Bring HTML source context, shared ontologies, human review and dataset delivery into one workflow for your training data team.
15X
Faster HTML Annotation
60%
Free Up AI Engineers’ Time
5X
Lower AI Development Costs

Annotation types for product webpages

Combine exact visible-text spans with semantic relationships and task-defined properties.
Exact text boundary of a product name in HTML

Product field spans

Select one contiguous, non-overlapping text range for each product field. Assign its class while preserving the exact visible source characters.

Field relations and properties

Connect a specification name to its value within the same HTML page. Add required properties to describe field roles or human-entered normalized values.
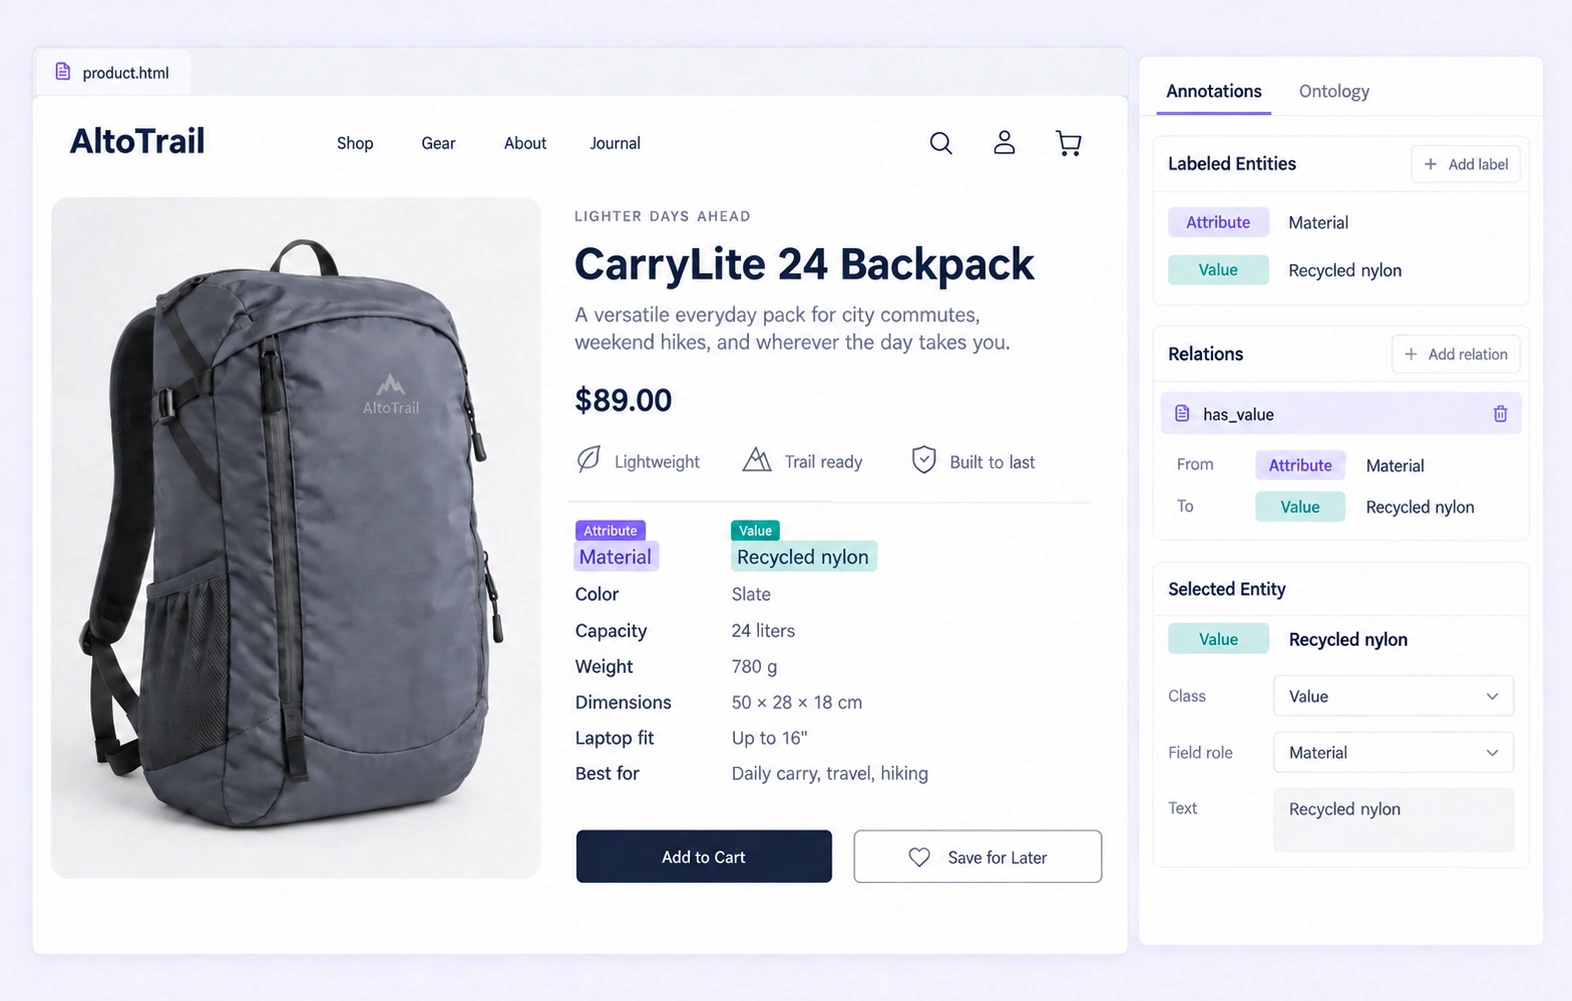
HTML specification relation with field properties

Product Page Information Extraction FAQs

What is product page information extraction annotation?

It labels the visible product fields that a model should extract from a webpage, such as a name, brand, model, price or specification value. Unitlab keeps those labels connected to the uploaded HTML snapshot for training and evaluation.

Which product fields can I label?

Define entity classes for the visible fields your dataset requires. Common examples include product names, brands, model identifiers, prices, availability, materials, dimensions and other stated specifications.

Can I distinguish a sale price from a list price?

Yes. Use different classes or a defined price-role property, and inspect the surrounding offer text. Preserve the actual source value rather than assuming every amount on the page describes the main product.

Can I link specification names and values?

Yes. Annotate each visible name and value as a separate text entity, then create an ontology-defined relation between them within the same HTML page. The relation records the connection your extraction task needs.

Can I record normalized product values?

Yes, when your ontology includes suitable properties. Annotators can enter reviewed normalized values while retaining the selected source text. This workflow does not automatically infer or normalize product attributes.

Do I upload product pages or provide live URLs?

The HTML workflow uses uploaded .html or .htm snapshots. Annotators review the rendered saved content; it is not a live website crawler or a browser session that follows links and changes the page.

Does Unitlab scrape products or extract every field automatically?

This solution prepares and reviews human-labeled extraction examples. It does not imply automatic crawling, product matching or automatic field extraction. Your downstream model can use the reviewed labels according to its training requirements.

How can reviewers catch labels attached to the wrong product?

Review the selected text in its rendered context, including nearby titles, offer details and recommendations. Contextual comments and the configured review workflow help return incorrect occurrences or ambiguous field roles for correction.

Can I export the labeled product pages?

HTML annotations support JSONL and Unitlab Unified Export Format. Exports preserve supported source identity, text-anchor information, entity labels, properties, relations and item properties for downstream dataset preparation.